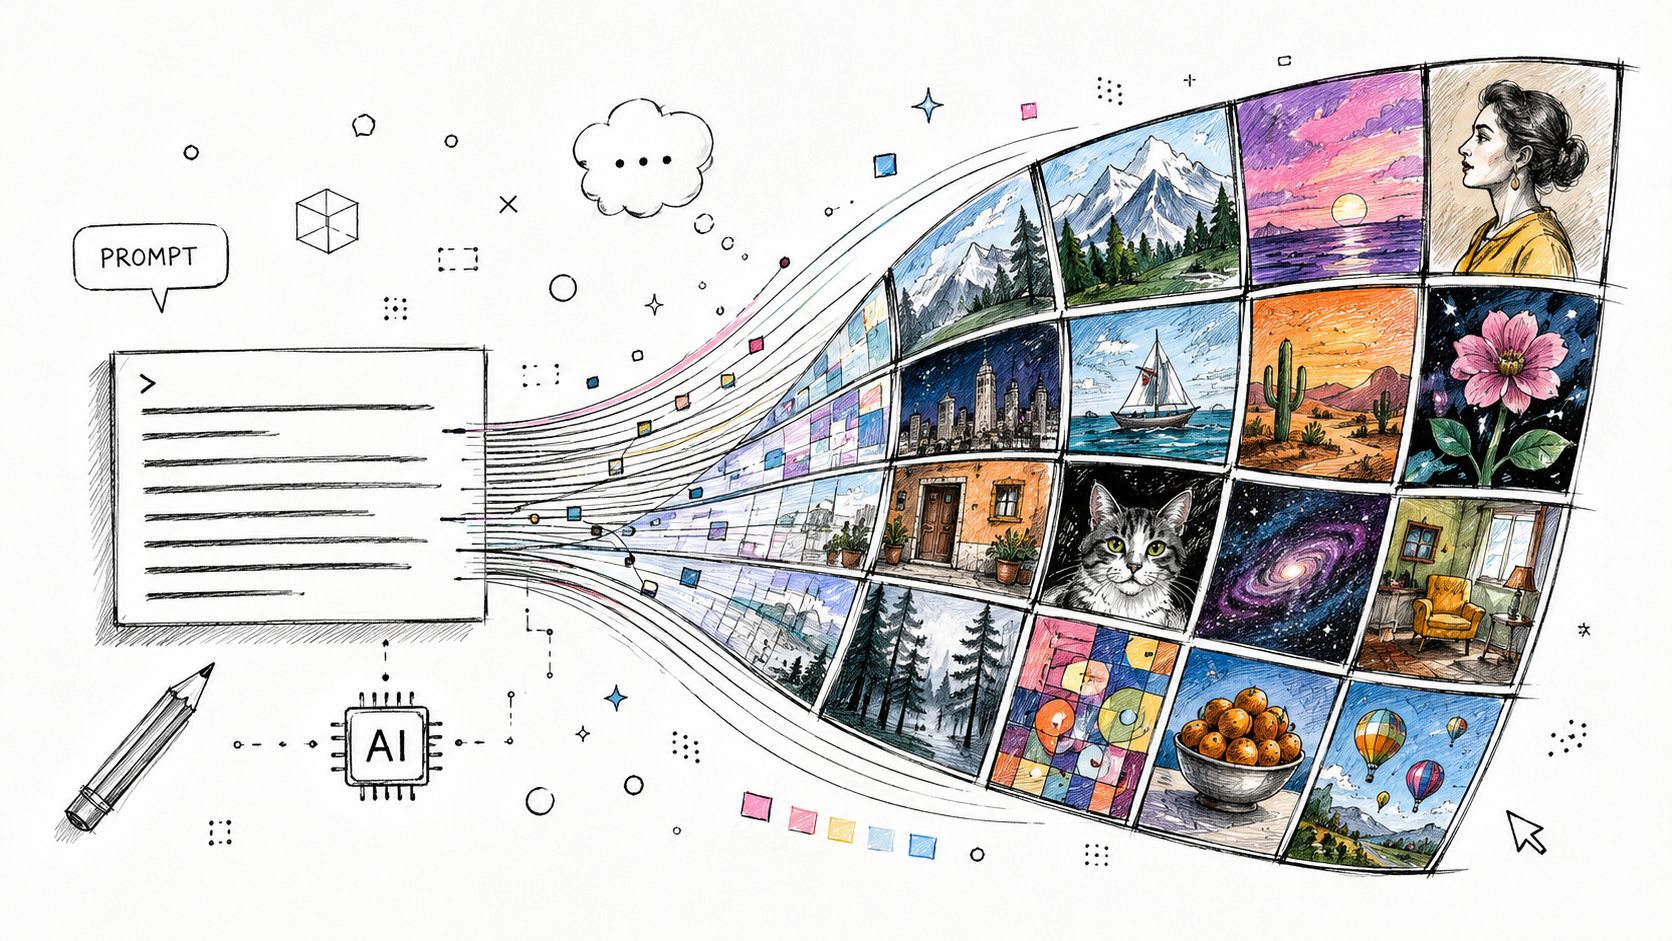
Stable Diffusion is a powerful AI model for generating images. It generates any kind of visuals from text descriptions. Such descriptions are called "prompts." Imagine typing "a cat wearing a top hat in a spaceship." Then, the AI creates a picture just like that! And the more precise a prompt is - the more the image is closer to what you have in mind. At least, usually.
But what if you want to create images in a specific style or with unique elements? That's where training your own Stable Diffusion model comes in. This article guides you through the process step-by-step.
How I Approached Training Your Own Stable Diffusion Model
This guide takes a practical view: most readers do not need to pretrain a foundation model from zero. They need to adapt an existing checkpoint so it can reproduce a visual style, a product, a character, or a narrow subject reliably. That is a very different problem from the original Stable Diffusion training effort, which drew from curated subsets of LAION-5B; the underlying dataset itself contains 5.85 billion CLIP-filtered image-text pairs, including 2.32 billion English-language pairs, and the first public Stable Diffusion release arrived on August 22, 2022 according to the Latent Diffusion Models paper summary.
I evaluated the workflow through the lens of a first real training run: what a beginner can set up without a research team, where GPU limits usually bite first, and which path gives the best quality-to-effort ratio. In practice, that ruled out training from scratch for almost everyone. It also pushed LoRA higher than full checkpoint training for a first project, because it is faster to iterate, lighter to share, and easier to undo if the results drift.
I also treated a training path as unsuitable for beginners if it required large custom infrastructure, vague dataset standards, or too much guesswork around evaluation. Success here means something concrete: the model should generate images that match the target subject or style in multiple prompts, without collapsing into near-duplicates, broken anatomy, or obvious overfitting.
Understanding the Basics: How Stable Diffusion Learns
For this article, the useful mental model is simple: you start with an existing Stable Diffusion base model, prepare image-caption pairs, choose whether to train a lightweight adapter or a full model, run training for several passes over the dataset, and keep checking sample outputs to see whether the model is learning the right visual concepts.
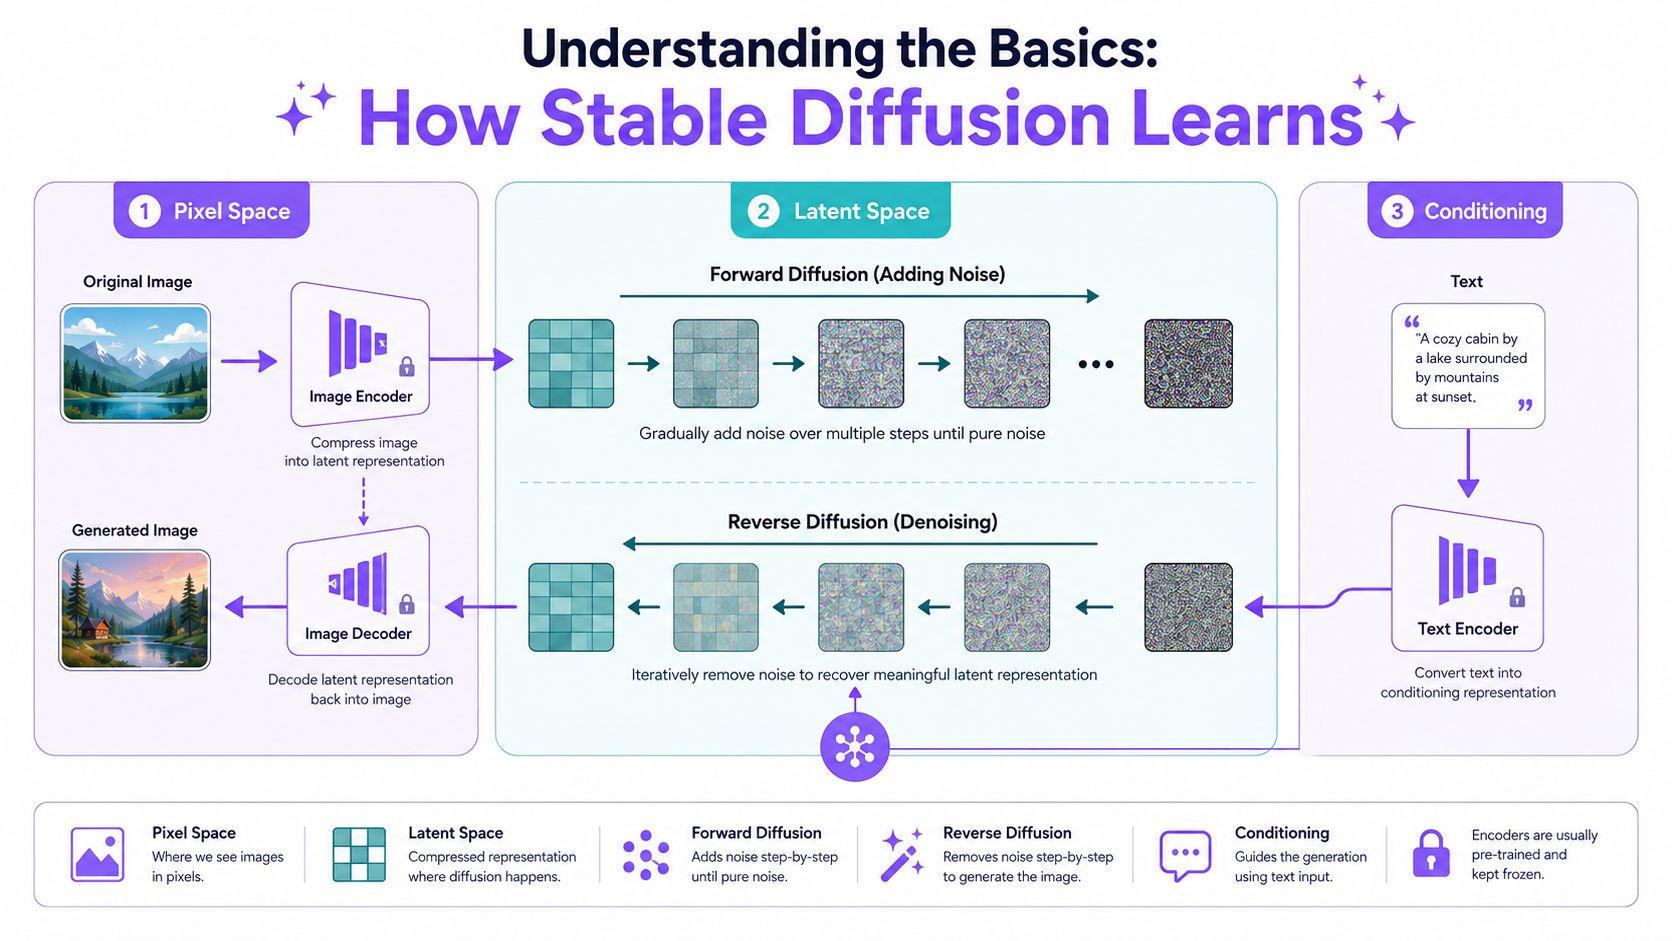
A base model is the general model you build on top of. It already knows broad relationships between text and images because it was trained on huge image-text corpora. The original Stable Diffusion line was not trained on one giant pile of images in a single pass; documented recipes used staged training on different LAION subsets, including 256×256 and later 512×512 phases, as described in the Stable Diffusion training paper. That scale matters because it explains why most individuals should fine-tune instead of trying to recreate the whole thing.
There are three common training paths:
- Training from scratch: building a brand-new model on a massive dataset. This is a research-scale task, not a practical weekend project.
- Full fine-tuning: updating many or all model weights from an existing checkpoint. This gives maximum control, but it costs more VRAM, time, and storage.
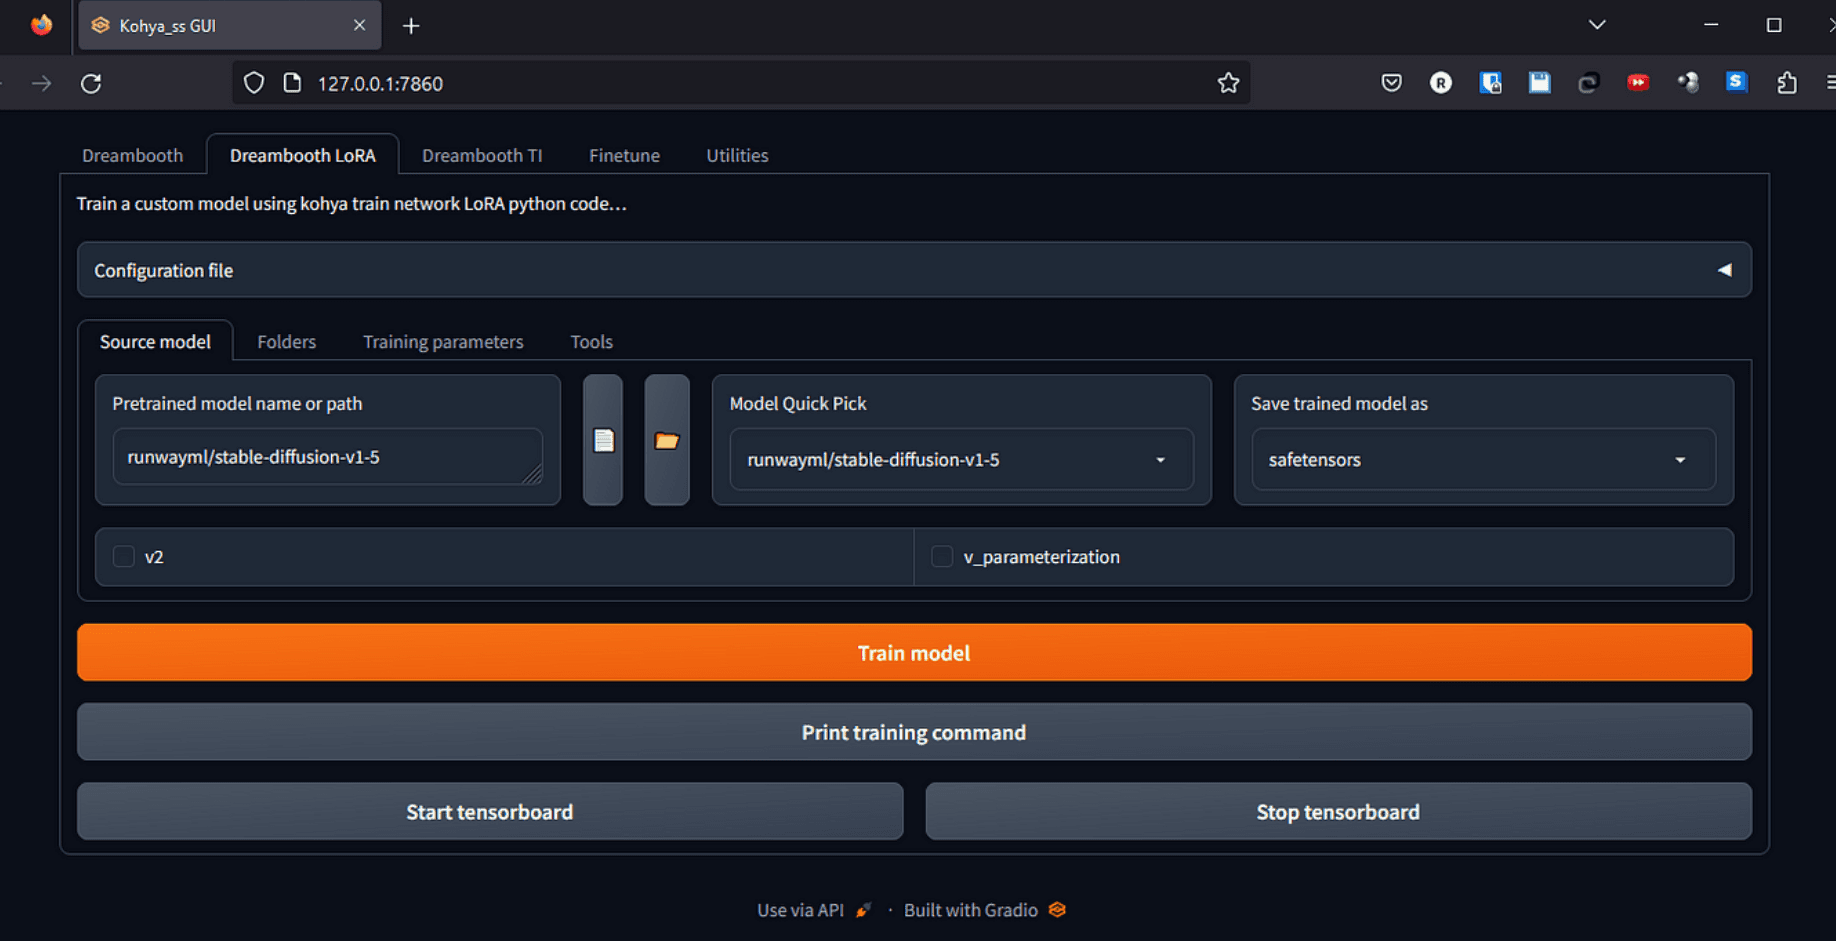
- LoRA training: learning a much smaller adapter that changes how the base model behaves without replacing the whole checkpoint. This can be a good starting point.
Your dataset becomes a set of training pairs: one image plus one caption that describes what the model should associate with that image. If the image shows the same person in different lighting, angles, and clothing, your captions help the model learn what is essential and what is incidental. In my experience, weak captions cause more confusion than slightly imperfect images. If the text says “red jacket” but the image is mostly about a face, the model often learns the wrong emphasis.
Most readers trying to build your own stable diffusion model are really trying to adapt an existing model, not invent a new image model family. That is good news: fine-tuning an established checkpoint or training a LoRA is dramatically cheaper than reproducing the original frontier-scale effort, which has been widely reported as requiring roughly 150,000 GPU hours on 256 A100s according to public accounts summarized in this Stable Diffusion overview. If you want inspiration for a very specific aesthetic target, this example of Ghibli-style outputs over at WebscrapingHQ is a useful reminder that a central challenge is not generation alone, it is getting consistent style behavior from your training data and captions.
Steps to Train Your Stable Diffusion Model
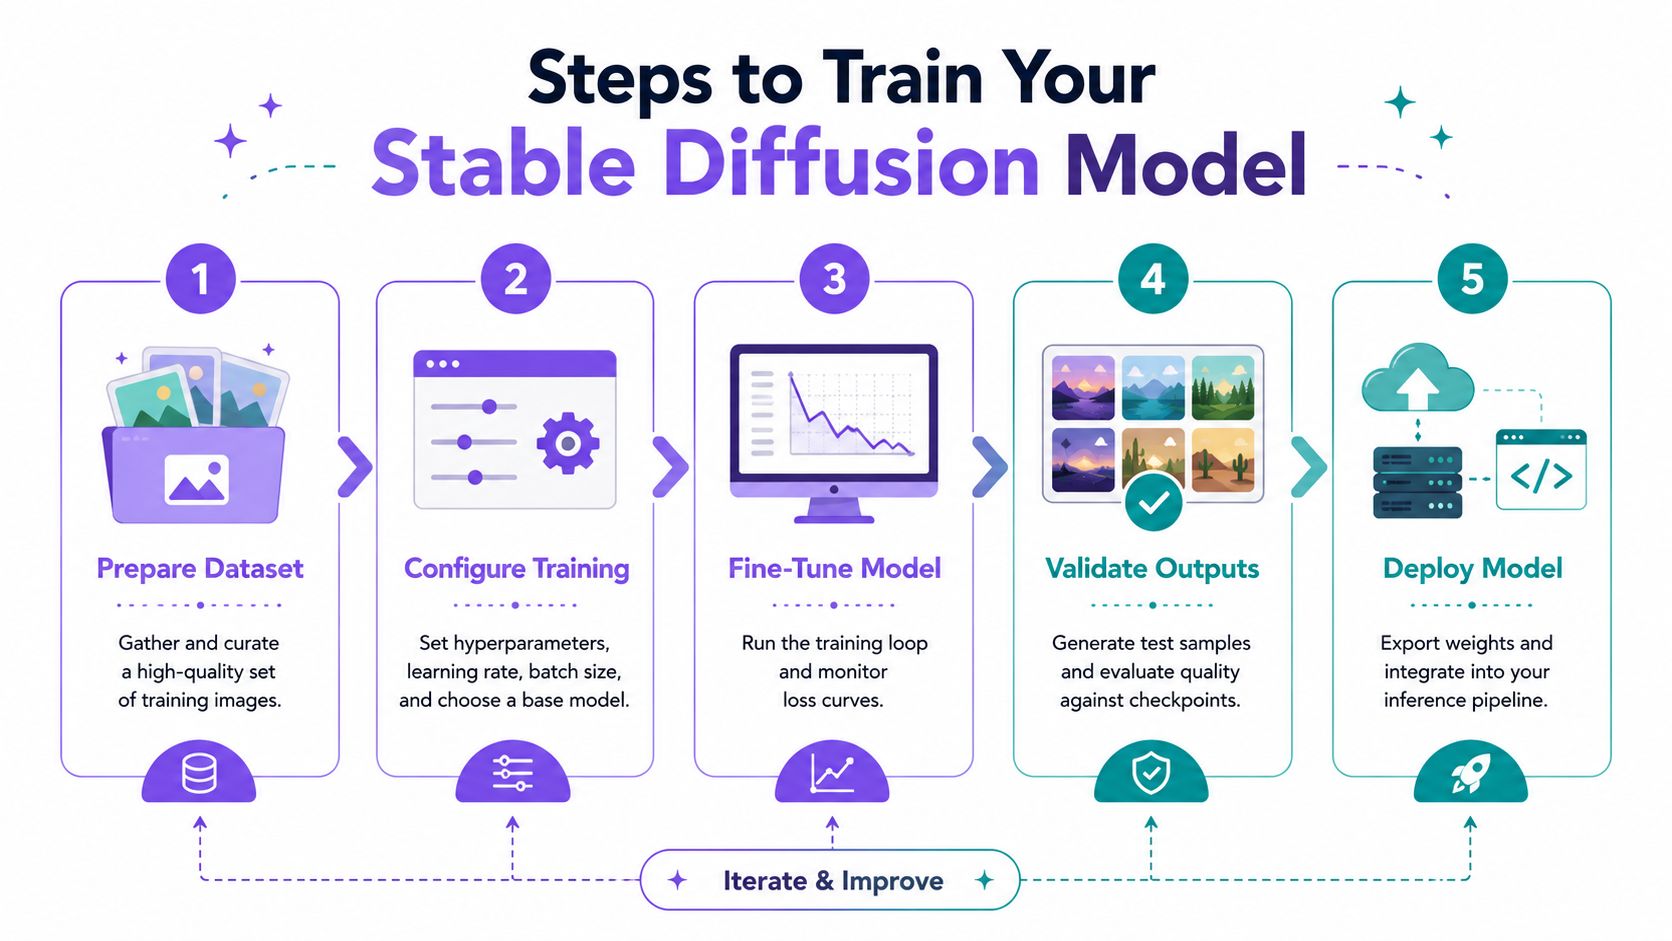

Dataset selection and captioning
Start with a dataset that matches one clear goal. If you want to teach a style, collect images that share that style but still vary in composition, subjects, and lighting. If you want to teach a specific character or product, prioritize identity consistency across many angles and contexts.
As a rough rule, a small LoRA can start learning from 20-50 strong images for a single subject, though results improve when those images are varied and well-captioned. For broader style work, 100-300 images is a more comfortable range. A few hundred images is still manageable for a solo workflow, but thousands of weakly labeled images usually create more cleanup work than benefit.
Captions matter as much as image selection. Use short, factual descriptions that identify the subject, style cues, camera framing, clothing, background, or medium only when those details are important. I have found that overdescribing every image can backfire; if every caption includes irrelevant words, the model starts attaching those words to everything. Keep the phrasing consistent, especially for the thing you want the model to learn.
Quality checks before training:
- Remove duplicates and near-duplicates.
- Remove images with heavy watermarks, unreadable crops, or contradictory content.
- Keep aspect ratios only if your training tool handles bucketing well; otherwise crop deliberately.
- Make sure captions describe what is visible, not what you wish were visible.
Environment setup
Training works in either a cloud notebook or a local machine, but the right choice depends on how often you plan to iterate.
- Google Colab is the fastest path for a first run because setup is lighter and GPU access is built in. Colab’s official environment details and notebook workflow are documented on the Colab platform.
- Amazon SageMaker makes more sense if you want repeatable managed jobs, storage, and cleaner scaling beyond a one-off notebook. AWS documents that stack in the SageMaker service guide.
- Local training gives the most control, especially if you already have a CUDA-ready NVIDIA GPU and enough VRAM, but dependency issues are more likely.
For beginners, I usually recommend Colab first. It is easier to test a dataset, fail cheaply, and rerun with better captions than to spend hours debugging a local environment before you even know whether the dataset is good. If you already train regularly, local or SageMaker setups become more attractive because you are not fighting session limits.
There is an entire tutorial on using Stable Diffusion on Colab (but similar stages apply to SageMaker). Link: Google Colab tutorial
Choosing a base model or LoRA
Practitioners should decide between LoRA training and full fine-tuning, not between dozens of model names.
A base model is best when you need broad generalization and want your training to inherit a strong default understanding of prompts, composition, and rendering. Your choice here should follow your target output: use a photorealistic base for product shots or portraits, and use an illustration-oriented base if your goal is stylized art. Public summaries of the Stable Diffusion family note that early versions were trained natively around 512×512, while later variants moved toward 768×768 training for stronger high-resolution coherence, as outlined in this Stable Diffusion background overview. That is why model choice and target resolution are linked.
A LoRA is the practical default when:
- you want to teach a character, object, face, or style,
- you have limited GPU memory,
- you want a small file that is easy to share or stack with other adapters,
- you expect to retrain several times before the dataset is final.
A full fine-tune is worth the extra cost when:
- you need deeper behavioral changes than an adapter can provide,
- you are building a model for one narrow domain and control the deployment environment,
- you can afford longer runs, more checkpoints, and more storage.
Quick comparison:
- Training time: LoRA is usually much faster.
- GPU demand: LoRA is lighter; full fine-tuning pushes VRAM much harder.
- File size: LoRAs are tiny compared with full checkpoints.
- Sharing: LoRAs are easier to distribute and combine.
- Best fit: LoRA for character/style/object adaptation; full fine-tune for heavier domain rewiring.
If you are using the Hugging Face ecosystem, the Diffusers training documentation is the best starting reference because it covers both fine-tuning patterns and the assumptions behind the tooling.
Preprocessing
Before training, make the dataset boring in the best possible way: consistent, clean, and predictable.
- Resolution: Use 512×512 when compute is tight, when you are training on older SD 1.x-era bases, or when your subject does not require high-detail structure. Use 768×768 when the base model expects it or when style and coherence at larger image sizes matter more than speed.
- Cropping and bucketing: Preserve the subject. Aggressive center crops often remove the exact detail you are trying to teach.
- Normalization and formatting: Follow the requirements of the script or framework you use; most common pipelines document expected image handling in the Diffusers training guides.
- Augmentation: Use it sparingly. Horizontal flips can help for some styles and products, but random color shifts may teach the wrong palette.
Two preprocessing mistakes show up constantly. First, datasets are often too repetitive, which makes the model memorize one framing instead of a concept. Second, captions are often too generic, which makes the model learn almost nothing specific. I would rather train on 40 carefully labeled images than 400 sloppy ones.
Training configuration
Before you start the run, decide what each major setting is supposed to control.
- Learning rate: how aggressively weights update. Too high and the model overshoots, producing unstable or distorted outputs; too low and progress is painfully slow.
- Batch size: how many samples the model sees before an update. Larger batches can stabilize learning but require more VRAM.
- Epochs: how many times the model sees the full dataset. More epochs increase learning, but they also increase the chance of memorization.
- Resolution: affects both quality and compute cost.
- Checkpoint frequency: how often to save intermediate states so you can roll back to the best version.
At a high level, if you have limited VRAM, you usually lower batch size first, then use gradient accumulation if your script supports it. If your outputs are barely changing, increase total training time carefully. If they are getting too literal and repetitive, reduce epochs or stop earlier.
A simple beginner logic:
- Small subject LoRA with limited hardware: start conservative and save checkpoints frequently.
- Style LoRA with broader data: use more varied captions and expect more steps before the style becomes obvious.
- Full fine-tune: plan for more storage, slower experimentation, and tighter monitoring.
Running training
Once the run starts, the model processes batches of image-caption pairs and updates its weights repeatedly. One epoch means it has seen the whole dataset once. During each epoch, the training script compares the model’s predicted noise or image representation against the target and pushes the weights in a direction that reduces error.
What to configure before pressing start:
- dataset path and caption format,
- base model checkpoint,
- LoRA or full fine-tune mode,
- resolution,
- learning rate,
- batch size and gradient accumulation,
- number of epochs or max training steps,
- output directory and checkpoint interval,
- validation prompts for sample generation.
What to save during the run:
- regular checkpoints,
- training logs,
- preview generations from the same fixed prompts,
- the exact settings file or notebook cell values you used.
That last point matters more than people think. On my first successful run, the biggest time-saver was not a magical parameter choice; it was being able to compare checkpoint 4, 6, and 8 with the same prompts and then return to the one that looked best. Without fixed prompt comparisons, it is easy to convince yourself the model is improving when it is just changing.
Here is an extensive video tutorial on the whole process of training a model in Stable Diffusion (I found it useful when I tried to train my first one):
Evaluation
Do not judge progress by loss alone. Loss can go down while image quality gets worse in the ways you care about.
Instead, evaluate with a small set of repeatable prompts:
- one prompt close to the training data,
- one prompt that changes pose or composition,
- one prompt that places the subject in a novel context,
- one prompt that tests whether the style transfers without copying.
Good signs:
- the target subject or style appears consistently,
- outputs still vary across seeds,
- anatomy, structure, and prompt-following remain intact,
- the concept works outside the exact scenes in the dataset.
Overfitting signs:
- generated images look like near-clones of training examples,
- backgrounds repeat unnaturally,
- the same face angle or composition appears over and over,
- prompts outside the dataset style break badly.
If that happens, stop early, roll back to an earlier checkpoint, reduce epochs, improve caption specificity, or add more varied images. If the model learned the wrong thing, caption mismatch is usually the first place to check. If it learned almost nothing, the dataset may be too small, too noisy, or too inconsistent.
Tools and Resources for Training Stable Diffusion
- Hugging Face Diffusers: A library that simplifies working with Stable Diffusion and other diffusion models, providing tools for training, fine-tuning, and inference. Hugging Face Diffusers
- Google Colab: A free cloud-based platform that offers access to GPUs, making it easier to train AI models. Google Colab
- Amazon SageMaker: A cloud machine learning platform that provides tools and resources for training and deploying AI models. Amazon SageMaker
- Civit.ai has hundreds of pre-existing models, LoRas, sets of data and useful information. Link: Civit.ai
Unlocking the Potential of AI with Writingmate
Ready to explore the world of AI image generation beyond Stable Diffusion? Writingmate offers a full platform to experiment with many cutting-edge AI models. It includes:
- DALL-E: Another powerful image generation model known for its ability to create realistic and imaginative visuals.
- Stable Diffusion Integration.
- GPT-4 and GPT-4 Mini are the latest versions of the GPT language models. They can generate human-quality text and help with writing, translation, code generation, and more.
- Claude, Mistral, and LLaMa are some other language models avaliable. Each has its strengths and capabilities. They can help you find the perfect fit for your projects.
Writingmate empowers you to harness the power of AI in one convenient web app. Start creating with the latest and greatest AI technology today!
Try it for free: Writingmate
Thank you for reading, I hope this tutorial was helpful and made things clear. For detailed articles on AI, visit our blog writingmate.ai/blog that we make with a love of technology, people and their needs.
Frequently Asked Questions
How do you train a diffusion model in practice?
For most individuals, learning how to train a stable diffusion model means fine-tuning an existing checkpoint or training a LoRA rather than building a new model family from zero. In practice, you start with a prepared dataset of image-caption pairs, choose a base model, set training parameters, and run repeated updates while saving checkpoints.
How do you actually train AI models without a research team?
You narrow the problem. Instead of trying to teach a model everything, you train it on one subject, one style, or one domain with clean examples and clear labels. That is why small, well-captioned datasets and repeatable evaluation prompts matter more than chasing frontier-scale infrastructure.
How to build Stable Diffusion from scratch?
Technically, it means collecting a massive image-text corpus, training the architecture at scale, and funding serious compute. For almost everyone, that is the wrong goal: public reporting around the original Stable Diffusion lineage points to frontier-level resources, so adapting an existing checkpoint is the realistic path.
Is it hard to train your own AI?
It is easier than pretraining a foundation model, but it is still easy to get mediocre results if your dataset is inconsistent or your captions are weak. The hard part is usually not pressing run; it is choosing the right training path, preparing data carefully, and stopping before overfitting ruins the outputs.
Should I use LoRA or full fine-tuning first?
Start with LoRA unless you already know you need deeper model changes. It is faster, cheaper, easier to share, and much more forgiving when your first dataset needs revision. Full fine-tuning is better reserved for specialized workflows where adapter-level changes are not enough.
Sources
- Google Colab tutorial
- Hugging Face Diffusers
- Google Colab
- Amazon SageMaker
- Civit.ai
- Writingmate
- Writingmate blog
Written by
Artem Vysotsky
Ex-Staff Engineer at Meta. Building the technical foundation to make AI accessible to everyone.
Reviewed by
Sergey Vysotsky
Ex-Chief Editor / PM at Mosaic. Passionate about making AI accessible and affordable for everyone.
Frequently Asked Questions
Sources
Written by
Artem Vysotsky
Ex-Staff Engineer at Meta. Building the technical foundation to make AI accessible to everyone.
Reviewed by
Sergey Vysotsky
Ex-Chief Editor / PM at Mosaic. Passionate about making AI accessible and affordable for everyone.