Type a topic, click generate, get four paragraphs that say nothing. I've done that more times than I'd like to admit, and I bet you have too. The text is grammatical, it's confident, and you still can't send it. Here's the thing: the generator usually isn't the problem. The brief is.
My name is Artem, and I run the Writingmate blog. I spend a large part of my week giving the same writing job to different AI models and watching which draft needs the least editing. This guide is what I've settled on: sort the job first, use one prompt template, and finish with a short edit check. If you just want to try it, the free AI text generator is where I'd start.
Below you'll get a job-type picker, a copy-paste template, a same-prompt model test you can run in ten minutes, and the five-minute check I run before anything gets published.
Why generic prompts give you filler
A language model predicts likely text. If your prompt is "write a blog post about remote work," the most likely text is the average of every remote work post it has seen: "In today's world, remote work has become increasingly popular." Nothing in your request pushes it away from the average.
Andrej Karpathy put the underlying issue well when he argued for "context engineering" over "prompt engineering":
"+1 for 'context engineering' over 'prompt engineering'. People associate prompts with short task descriptions you'd give an LLM in your day-to-day use." — @karpathy on X
That's the whole game for writing. A short task description gets a generic answer. The audience, your facts, the length and the tone are the context that makes the draft yours.
You'll see the same complaint in community threads. A r/ChatGPTPro thread on stopping ChatGPT from adding em dashes and other tells is a good example (I'm paraphrasing the thread, not quoting it): people spend their time stripping habits out of finished drafts instead of preventing them in the brief.
Anthropic's applied AI team says something similar in their Prompting 101 talk, embedded above. Their structure starts with the task and role, separates the changing inputs from the stable background, asks for a tone, and repeats the critical rules near the end, for example "only make claims supported by the source" and "say so instead of guessing." Those last two lines are exactly what a text generator needs when you hand it facts.
Pick the generator setting by job type
"Text" isn't one job. An email, a blog draft and a product description fail in different ways, so they need different inputs. Here's the picker I use.
Job | What you must pin | Typical failure | Length to ask for |
|---|---|---|---|
Recipient, one ask, deadline, relationship | Padded opener, vague ask | 80 to 150 words | |
Blog draft | Reader, thesis, outline, your examples | Safe, average, repetitive | One section at a time, 200 to 400 words |
Product copy | Fact sheet: specs, materials, sizes | Invented features | 50 to 120 words |
Social post | Platform, hook, one point, voice sample | Hashtag soup, fake excitement | Platform limit, minus 10 percent |
Summary | Source text, reader, what to keep | Dropped or invented details | Fixed ratio, such as 1 in 5 |
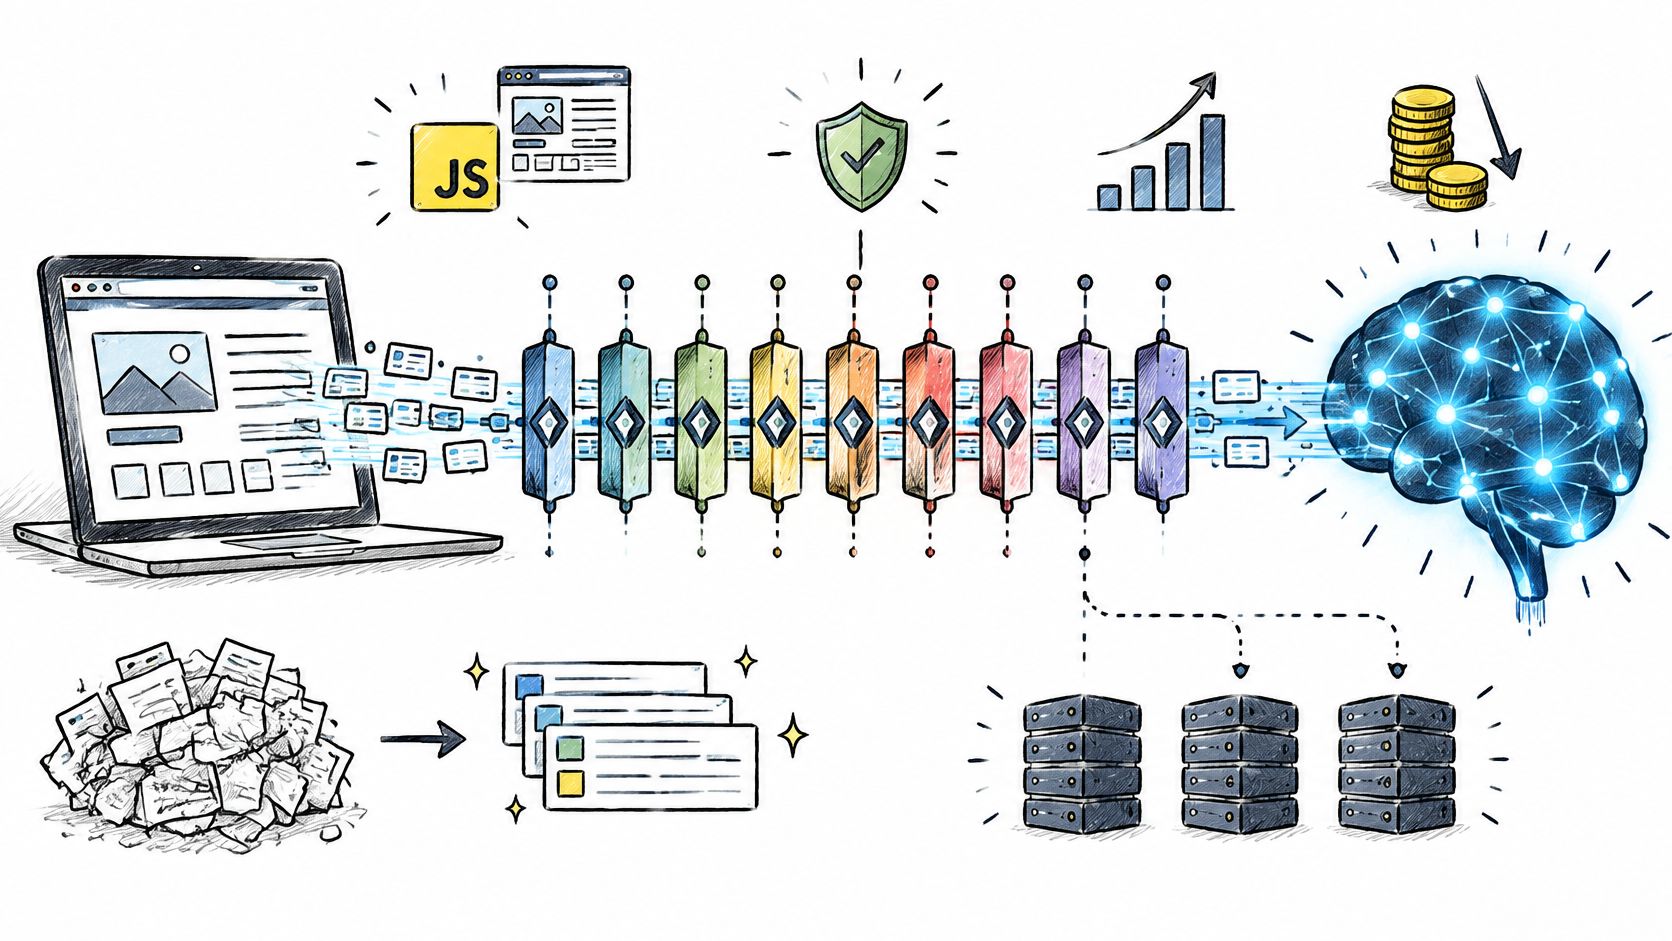
Two rules fall out of this table. First, anything with facts (product copy, summaries) needs the facts pasted in. Never ask the model to "know" them. Second, anything long (a blog draft) should be generated in sections, because quality tends to sag late in a long single-shot answer.
For summaries of long documents specifically, I wrote a separate walkthrough in the PDF summarizer guide, and for listings there's the product description fact sheet post.
The prompt template that pins audience, length and facts
This is the template I paste into the generator. Fill every bracket. If you can't fill one, that's the part of the draft that will come out as filler.
Job: Write a [email / blog section / product description / social post / summary].
Reader: [who they are, what they already know, what they want].
Goal: After reading, they should [one action or one idea].
Tone: [3 adjectives]. Match this sample of my writing: "[2 to 3 sentences]".
Length: [exact words or sentences]. No more.
Use ONLY these facts:
- [fact 1]
- [fact 2]
- [fact 3]
If a detail is not in the list above, leave a [PLACEHOLDER] instead of guessing.
Avoid: [phrases you hate, clichés, emojis, hashtags].
Output: just the text, no intro or explanation.
Let me explain the lines that do the most work.
- Reader and goal. "A busy ops manager who wants to know if this costs more than last quarter" produces a different email than "a customer."
- A voice sample. Two or three real sentences from your own writing beat any adjective list. This is the cheapest fix for flat voice.
- Exact length. "Short" means nothing. "110 words" gives the model a target you can check.
- Use ONLY these facts, plus the placeholder rule. This is the line that cuts invented numbers. It mirrors Anthropic's advice to restate "only claim what the source supports" and to prefer saying so over guessing.
- Avoid list. Add words you keep deleting. After a few drafts, your list becomes a personal style guide.
Here's a quick before and after. The weak prompt: "Write a product description for a ceramic mug." The pinned version gives the reader (gift shoppers), 70 words, and three facts: 350 ml, dishwasher safe, handmade glaze that varies per piece. The first returns "elevate your morning routine." The second returns text that can only say things you gave it. That's a real difference in editing time, even before you consider voice.
How I compared models on the same prompt
Here's what I checked, so you can repeat it. I don't publish a leaderboard here, because results change with every model update and your jobs aren't mine. I run a method instead.
- Pick one real job, such as a 120-word customer email with four facts.
- Paste the filled template into the free text generator, then run the identical text in Writingmate chat on two or three other models from the model picker.
- Don't tweak the prompt between runs. Different wording would make the test meaningless.
- Score each draft on four things: facts correct (all four present, none added), length within 10 percent, number of edits you'd make, and whether it sounds like the voice sample.
- Keep the model with the fewest edits for that job type, not the one with the fanciest prose.
Score | Draft A | Draft B | Draft C |
|---|---|---|---|
Facts correct, none added | yes / no | yes / no | yes / no |
Within length | yes / no | yes / no | yes / no |
Edits needed | count | count | count |
Voice match (1 to 5) | score | score | score |
In my experience, the pattern is consistent: fast, cheap models do fine on short emails and social posts, while longer drafts and voice-sensitive copy often read better on a stronger model. But I'd rather you confirm that on your own jobs than take my word for it. Switching between 200+ models in one place is the reason I do this in Writingmate; you don't need separate accounts to run the test. Check pricing if you plan to run it often.
The 5-minute edit check before you publish
Even a well-pinned draft needs a pass. I time myself, and one minute per item is enough. Sound familiar? It's the same discipline as proofreading, just aimed at the specific ways AI text goes wrong.
Minute 1: Invented facts
Highlight every number, name, date, quote and claim. Check each against your source list. If it's not in the list, delete it or replace it with a verified one. Be extra careful with "studies show" and "experts say," which usually point at nothing.
Minute 2: Repeated phrasing
Read the first three words of each sentence and paragraph. If four sentences start the same way, rewrite two. Search the draft for any word that appears more than three times, other than your topic. Models love repeating a favorite adjective.
Minute 3: Flat voice
Read the draft out loud. Where you'd never say the sentence, rewrite it. Swap abstract lines for something specific: a number, a name, a short example from your own work. Cut filler openers like "In today's fast-paced world" and the closing line that restates everything.
Minute 4: Meaning and promise
Does the draft do what the Goal line said? An email should contain exactly one clear ask. A social post should make one point. If the draft hedges everything, cut the hedges.
Minute 5: Format and last read
Check length against the target, fix formatting, remove leftover placeholders (you did ask for them, so search for the brackets), and read the first and last sentence once more. Those two carry most of the reader's impression.
If the draft fails minutes 1 or 3 badly, don't polish. Go back to the prompt, add the missing facts or a better voice sample, and regenerate. It's faster than rescuing weak text. For meaning-level rewrites of single sentences, the sentence rewriter guide has a two-minute check that pairs well with this one.
Common mistakes I still see
- Asking for 1,500 words in one go. Generate section by section and feed in the outline.
- Giving no facts and expecting accuracy. The model fills gaps with plausible guesses. That's its job.
- Editing to beat AI detectors. They're unreliable. Edit for the reader.
- Never saving the template. Keep one filled-in version per job type and just swap the facts.
- Judging on the first run. Test, find the failure, and add one line to the prompt to fix it. That's the iteration loop Anthropic's talk recommends too.
The bottom line
An AI text generator gives you what you brief it for. Name the job, pin the reader, length and facts, run the same prompt across a couple of models, and spend five minutes on the edit check. That routine takes a draft from "interesting but unusable" to something you'd actually send.
If you want to try it now, open the free AI text generator, paste the template, and fill in one real job. Tell me which model gave you the cleanest draft.
See you in the next one!
Artem
Frequently Asked Questions
Sources
Written by
Artem Vysotsky
Ex-Staff Engineer at Meta. Building the technical foundation to make AI accessible to everyone.
Reviewed by
Sergey Vysotsky
Ex-Chief Editor / PM at Mosaic. Passionate about making AI accessible and affordable for everyone.